 Shivali Sharma
Resume
Shivali Sharma
Resume
Case study · solo build, Rethink Systems Cohort 8
College students ask AI which career fits them and get fluent, confident, unverifiable answers. Nibble lets them try the actual work first, with an AI collaborator that sometimes gets things wrong, because spotting that is the skill.
Try Nibble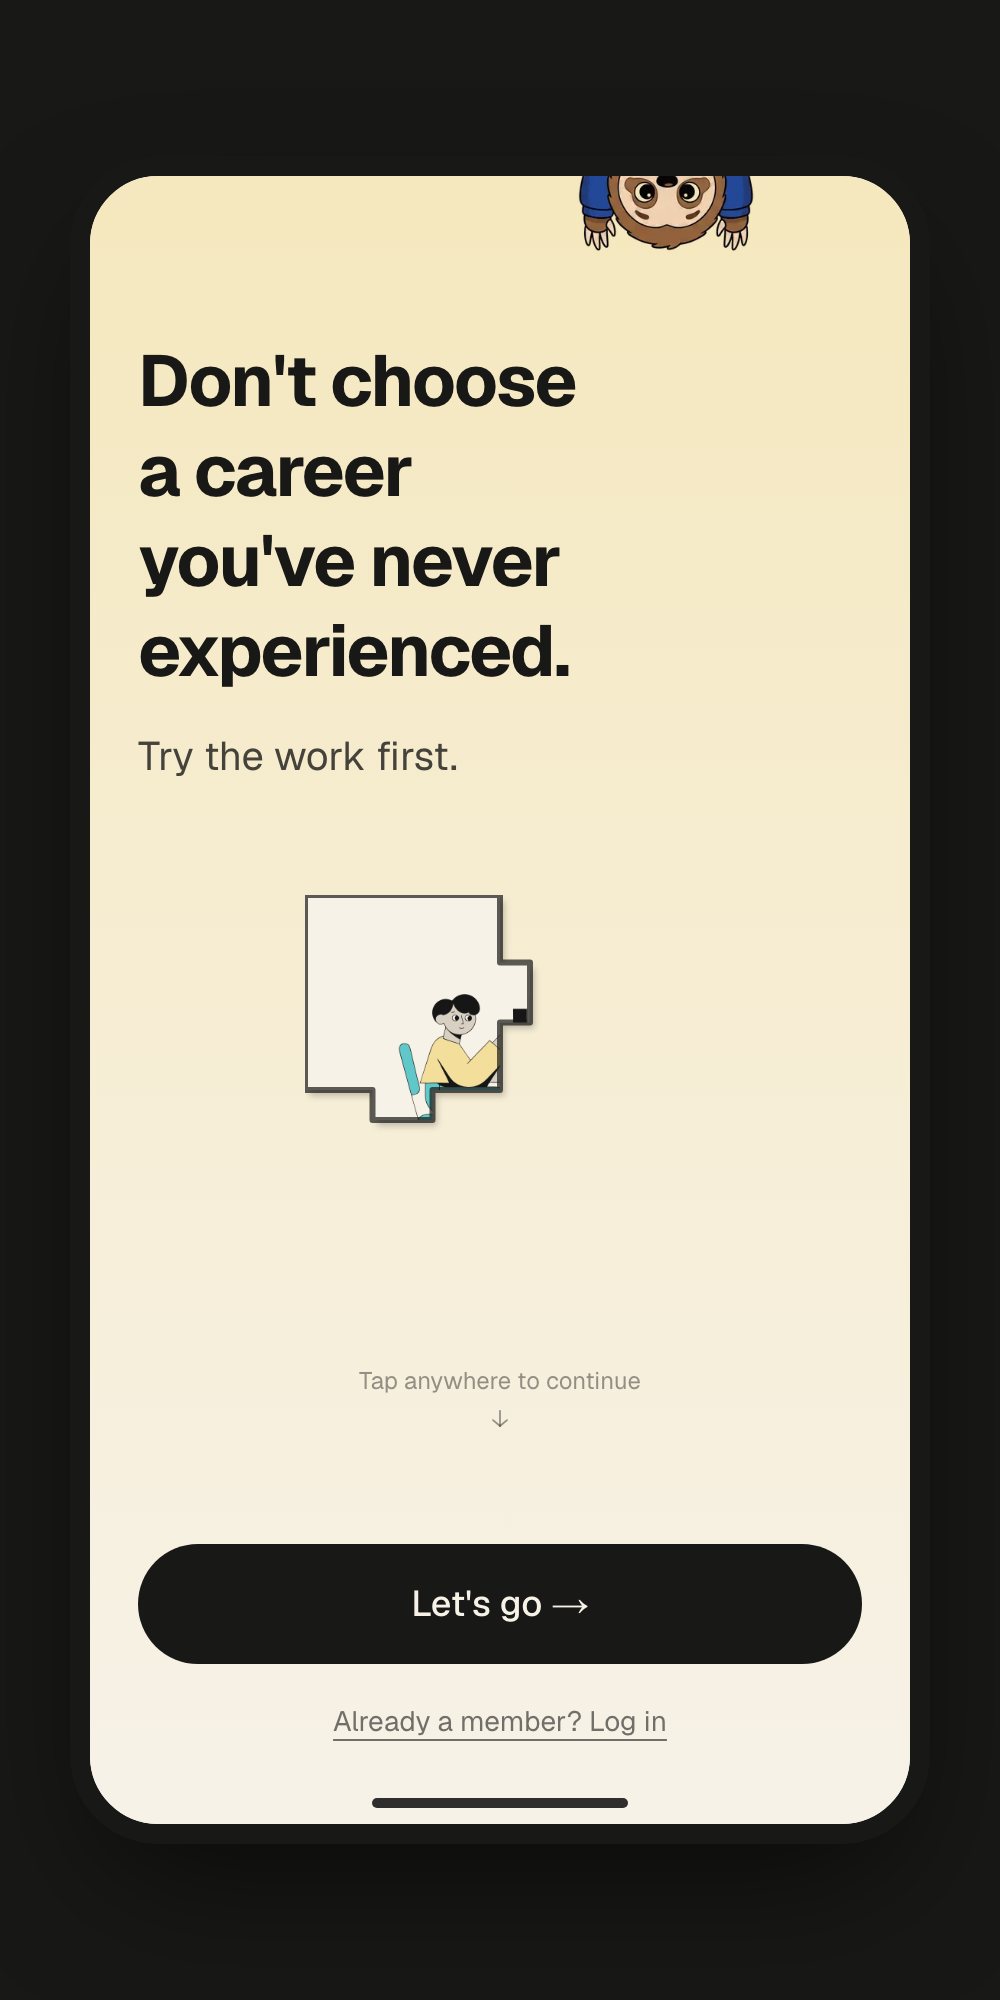
Build a new-age learning platform that takes non-technical people from "I don't understand technology" to "I can confidently use and build with it." Who the user is, what the problem is, what the MVP includes: all my call. The one hard requirement: a working MVP in the hands of 40 to 50 real users, with full-funnel tracking and iterations based on what they actually did.
Everyone's first instinct with this brief is working professionals. I mapped nine candidate users before choosing, and the choice came from a question that flipped the frame:
what if someone learns AI before they learn normal workplace habits?
That question surfaces the AI-native first-jobber, and one step earlier, the college student at the career direction decision: the moment "I don't understand technology" is actually decided, years before the first job. The habit is still forming, the need peaks near placements, and students are reachable directly without selling to an institution. A 24-person survey confirmed this is where the pain is loudest.
Career advice is abundant and free: listicles, day-in-the-life videos, salary reels, counsellors, and now AI. What is structurally absent is first-person contact with the work itself. India has roughly 100 thousand companies offering internships against 40 million students; real experience cannot arrive before the decision does.
And AI landed inside exactly this gap. Students ask it whether a career fits them and cannot evaluate the answer, because they have no experience to check it against. Trust gets set by fluency instead of accuracy. That makes this a judgement problem, not a guidance problem.
Nibble's core loop is doing short, real work: missions, not lessons. Inside each mission sits an AI collaborator that is deliberately imperfect. Sometimes its suggestion is solid; sometimes it is confidently wrong. The student's job is the same as it will be at work: use it, check it, decide.
Every mission feeds a Judgement Report scored on five dimensions: problem framing, evidence selection, AI trust calibration, verification, and reasoning. In eval terms, that report is a rubric-based, human-in-the-loop evaluation of how well a person collaborates with an unreliable model, and it runs automatically on every mission. And one deliberate restraint: no streak guilt. Continuity comes from a mission ladder, a concept dictionary and a cumulative report, never from shame mechanics inside a learning moment.
I set the pass marks in advance so the results could actually falsify me: mission gate conversion at least 50%, Mission 1 completion at least 60%, Mission 2 pull at least 40%, 7-day return at least 30%. A ₹99 plan was designed and deliberately kept off, so the funnel data stayed clean. Every step of a 9-step funnel was instrumented: 3,632 typed events in Supabase, mirrored to Mixpanel.
What the log actually said:
The discovery document tags every claim by how sure I am of it: Fact, Observation, Insight, Assumption, Hypothesis, User evidence, Decision. A reviewer can audit any page by its tags alone. I hold myself to the same standard here, so, honestly marked:
What's proven: real users chose to do simulated work over reading about careers, and the gate fear was disproved by the log.
What's designed but unproven: the report-share growth loop and the ₹99 price point. Both are bets, and they are labelled as bets.
What I'd do differently: guide the first unguided step sooner. The data said users don't fear commitment; they fear being alone right after it.
The full 17-page discovery PRD, with the funnel counts, the solution tree and every tagged claim, is available on request.
sshivali53@gmail.com